Tencent releases Hy4 flash weights for local deployment, two days after launch
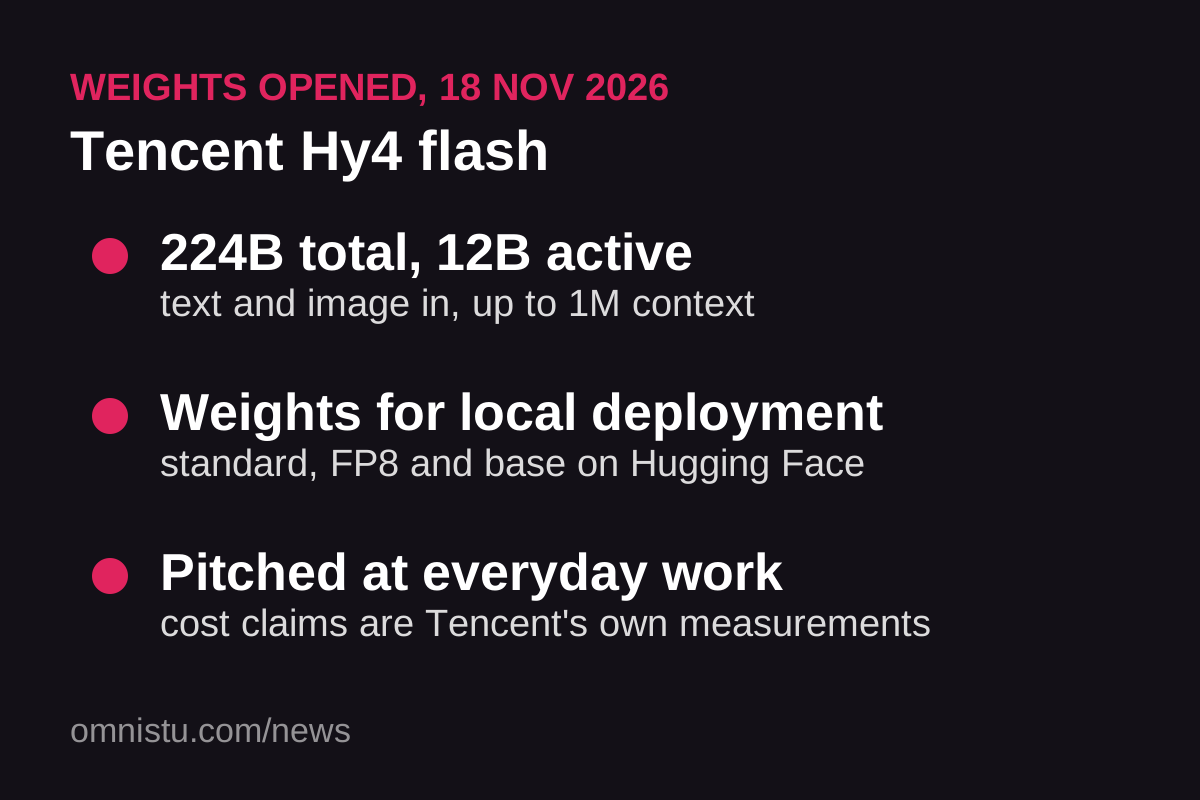
Two days after launching Hy4 flash on 16 November 2026, Tencent released the model's weights for local deployment. The standard, FP8 and base models are on Hugging Face, ModelScope and GitCode under the Tencent Hy License: 224B total parameters with 12B active per token, text and image inputs, and up to 1M tokens of context.
Tencent launched Hy4 flash on 16 November 2026 as the most cost-effective model in its Hy family, and released the weights on 18 November, TechNode reported, making good on its announcement that the weights would be opened. Developers can download the standard instruct model, an FP8 quantized version, and a pre-trained base model for further training, from Hugging Face, ModelScope and GitCode under the Tencent Hy License.
The model
Hy4 flash has 224 billion total parameters, including 64 billion "Engram" parameters, with about 12 billion active per token. It accepts text and image inputs, generates text, and supports a context window of up to one million tokens. A built-in five-layer drafter, DFly2, supports long-context speculative decoding, and Tencent says decoding exceeds 150 tokens per second. The model targets everyday productivity work: deep research, document processing, slide decks, simple front-end displays and computer use, with Tencent steering complex long-horizon engineering tasks to the larger Hy4.
Costs and claims, per Tencent's own measurements
API pricing is about $0.070 per million input tokens, $0.281 per million output tokens and $0.003 per million cached input tokens. On Tencent's internal WorkIndex benchmark, the company puts Hy4 flash's per-task cost at 1/13 of Hy4 Preview, 1/20 of Hy4 and 1/8 of DeepSeek-V4.1-Flash, and says it slightly outperforms the larger Hy4 Preview overall; in a blind evaluation with 85 internal users across 259 tasks, satisfaction was close to Claude Haiku 5.5. These are the company's own internal figures, not independent benchmarks. Tencent also said the model passed 50 trillion tokens of first-day usage, its own reported number.
Where to get it
Beyond the downloadable weights, Hy4 flash is available through Tencent Cloud TokenHub, WorkBuddy, Yuanbao, WeCom, QQ, ima and Marvis, with OpenRouter integration announced as coming soon. Tencent is offering free WorkBuddy access until 30 November and 50% off standard TokenHub pricing; Vercel's AI Gateway lists the model at 50% off through 29 November. The team says it plans frequent open-source iterations.
What to keep in mind
Performance, cost and usage figures come from Tencent's own announcements and internal benchmarks. The Tencent Hy License is the vendor's own license, so check its terms before commercial deployment; "open-weight" here does not mean OSI-approved open source. Long-context claims assume specific inference setups described in the repo.
- Tencent (16 November 2026): official launch announcement
- TechNode (19 November 2026): Tencent releases Hy4 flash model weights for local deployment
- GitHub: Tencent-Hunyuan/Hy4-flash README (model links and deployment)